← Back to research
layer: archive · research log
OCR & Object Recognition
Undergraduate research with Dr. Ning Yu · 2025
OCR pipelines for high-resolution image datasets, pairing classical computer vision with the Gemini API for context-aware recognition.
- Python
- Gemini API
- OpenCV
- NumPy
- Matplotlib
what I did
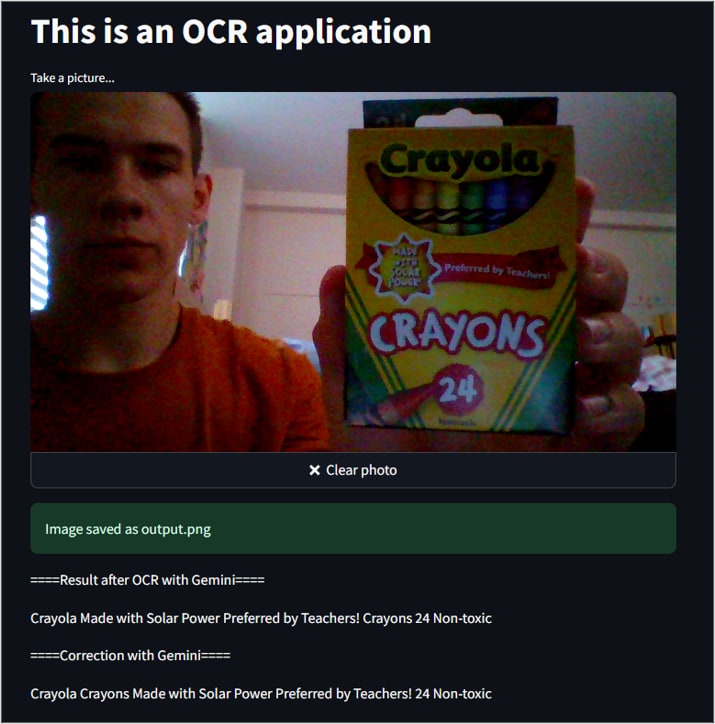
- 01Built a small OCR app: snap a photo, extract the text with Gemini, then run a second Gemini pass to correct it.
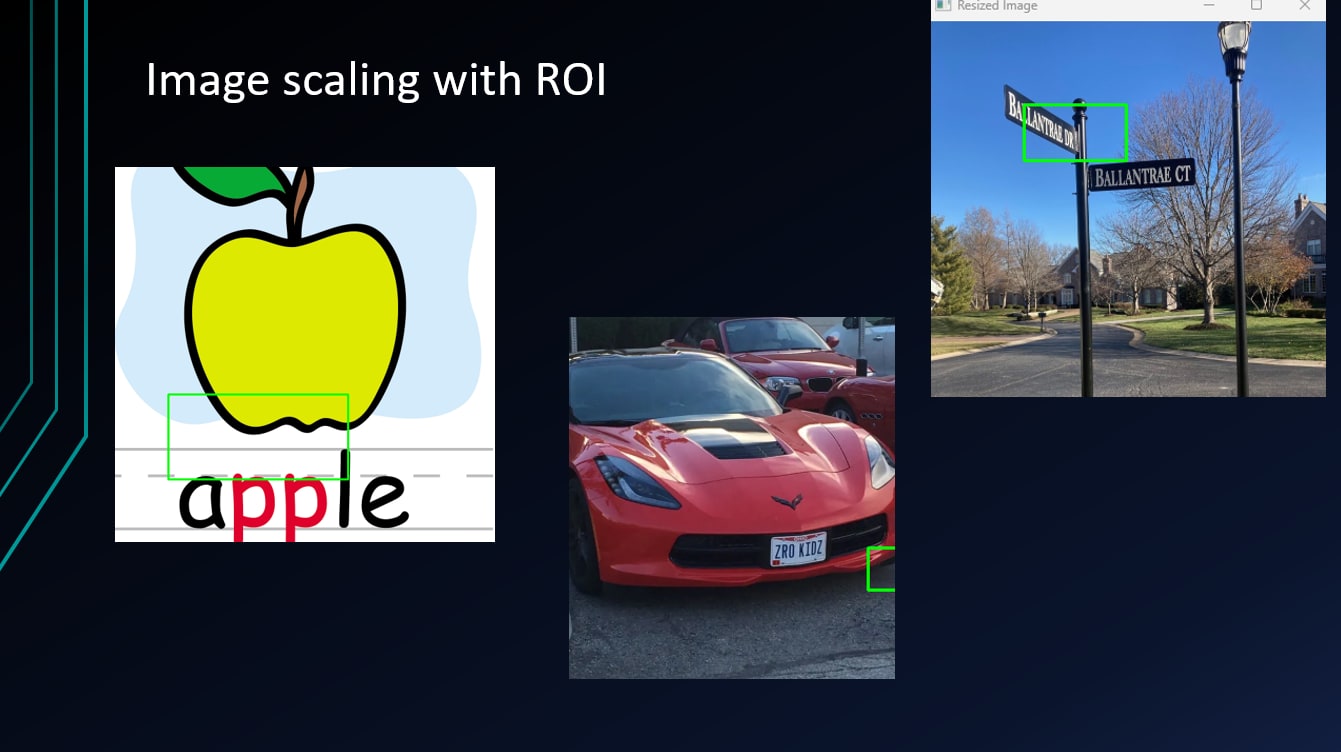
- 02Used region-of-interest boxes to find and scale text inside mixed images: drawings, cars and street signs.
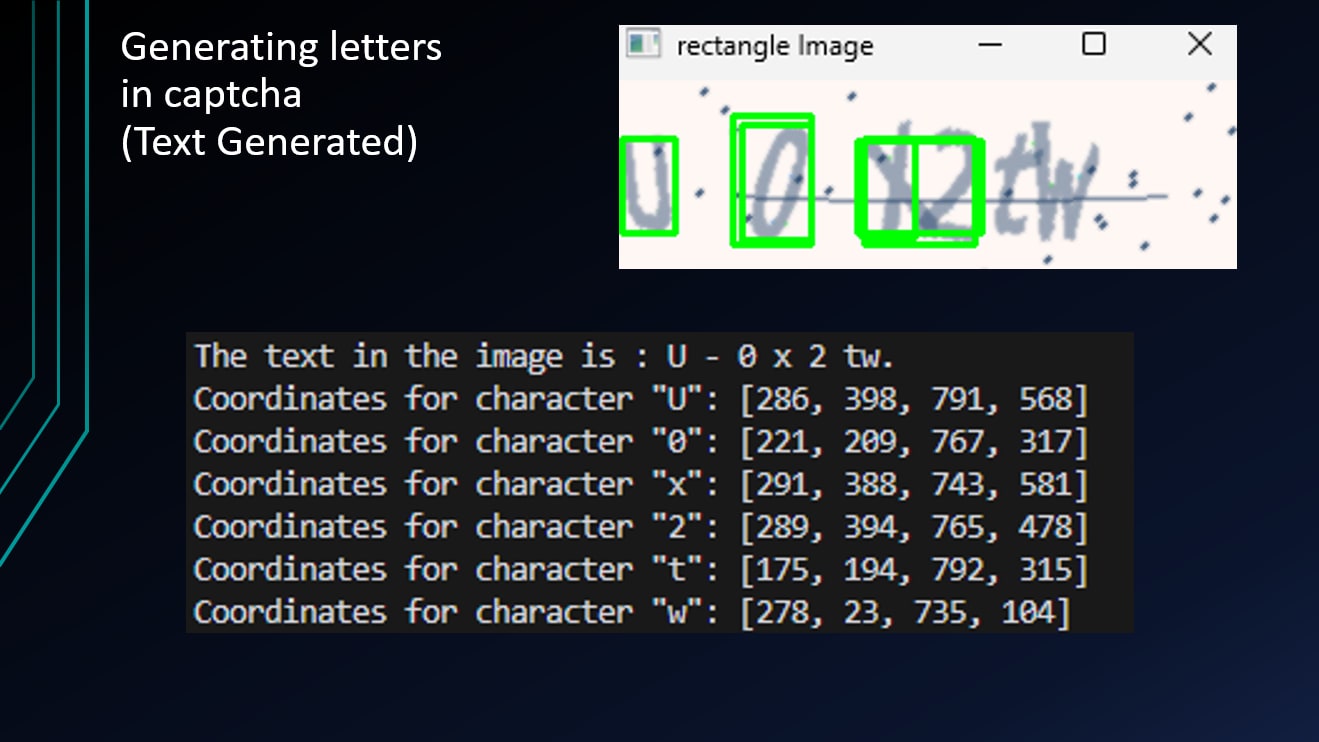
- 03Located each character in generated CAPTCHA text and returned its coordinates.
- 04Worked through diverse, edge-case-heavy visual data where off-the-shelf recognition falls short.
- 05Built the image processing layer with OpenCV, NumPy and Matplotlib.
from the work
next log
Mask R-CNN — Image Forgery Detection →